What has been tested
Four things, at four different levels of rigour. They are separated here because collapsing them into the word "tested" is how an engineering result comes to sound like a certification.
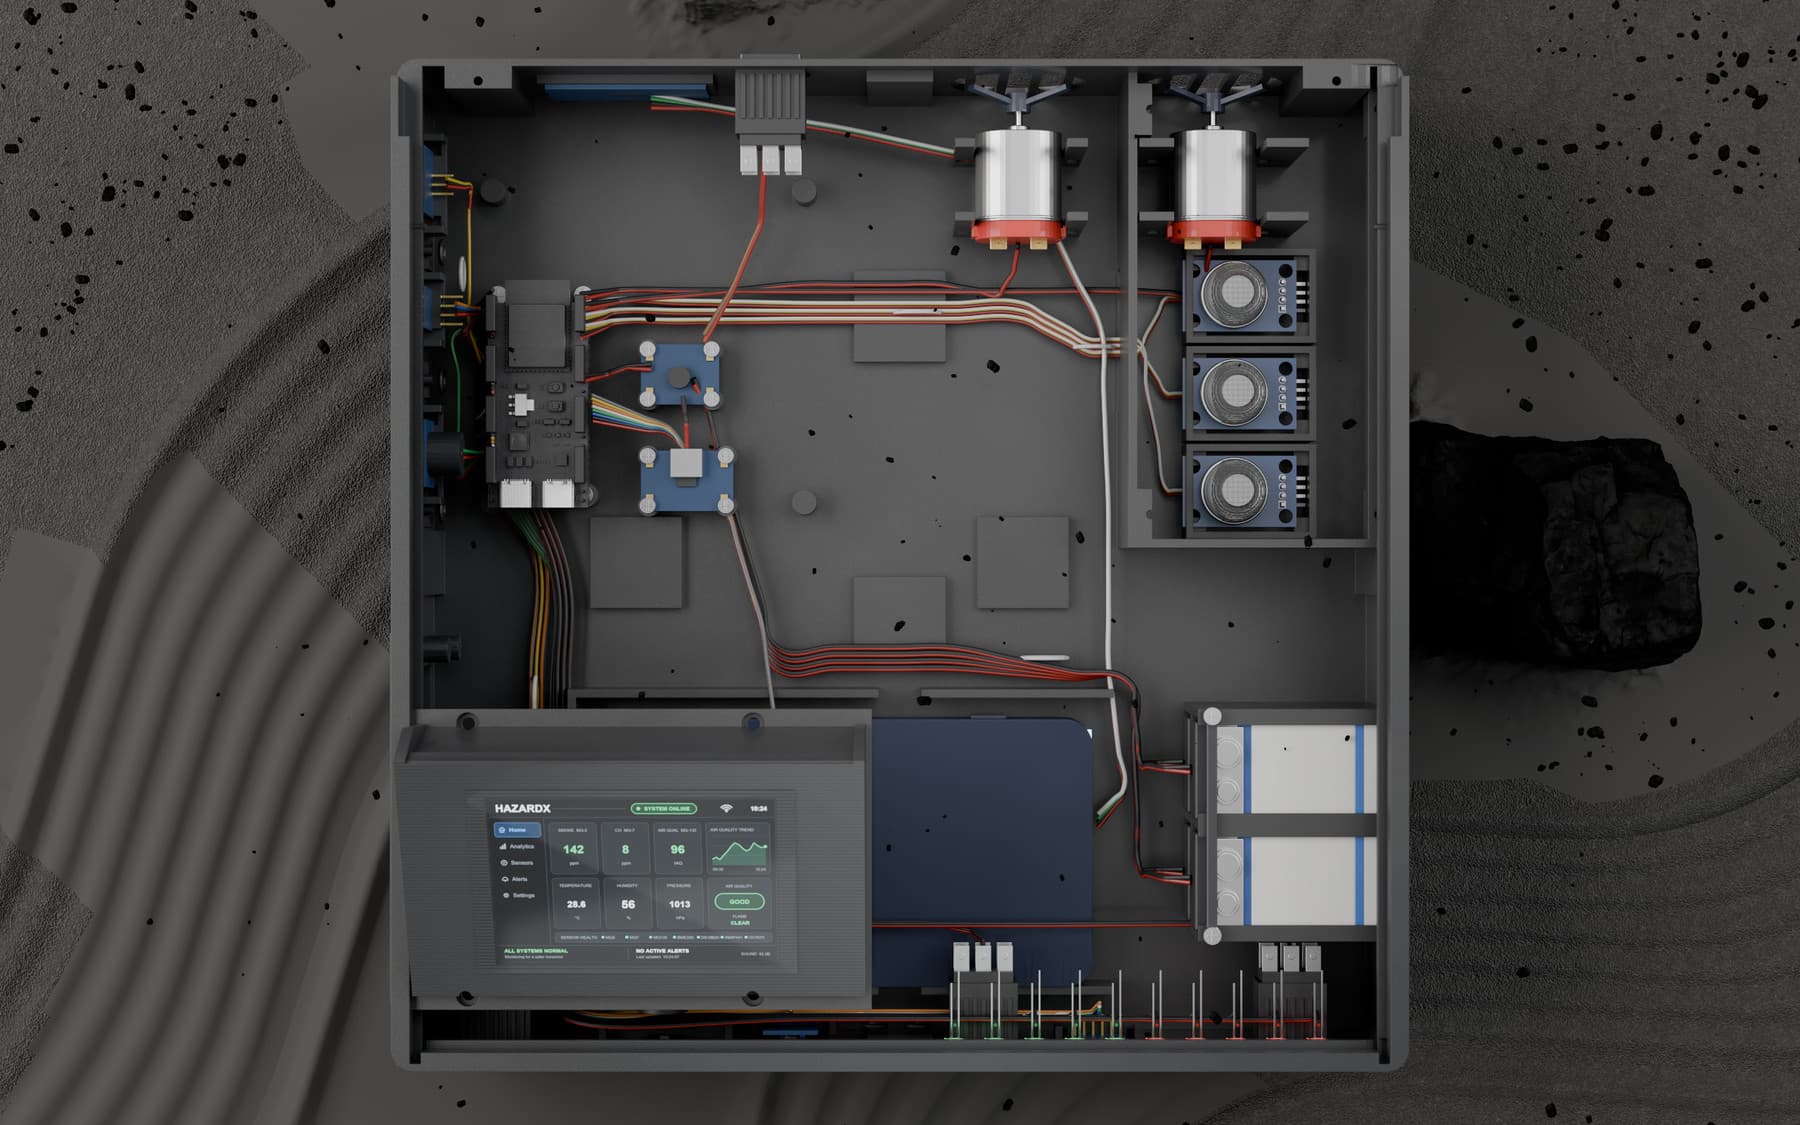
- Function, end to end. A reading leaves a sensing element, is classified on the node, drives the local alarm, reaches the ingest endpoint, appears on the dashboard, produces an incident record and can be answered with a remote command. This path has been exercised repeatedly and it works.
- Independence of the network. The local alarm has been tested with the uplink pulled. The node classifies and sounds without it, which is the single most important structural property of the design and the easiest one to verify.
- Response to induced events. The gas channels have been exercised against deliberate releases at bench scale - the ordinary workshop sources - and the thermal and vibration channels against heated and unbalanced test loads. This establishes that a channel responds and roughly how fast. It establishes nothing quantitative.
- Continuous running. Nodes have been left running on a test deployment for extended periods, which is what surfaces the failures that never appear in a two-hour bench session: drift, WiFi reconnection behaviour, and readings that silently stop changing.
What that testing does not establish
Being explicit about this is the point of the page.
It does not establish a detection rate. Knowing that the system caught a deliberate release in a workshop tells you almost nothing about the probability of catching an unplanned one, in a different room, with different airflow, at a different concentration.
It does not establish a false-alarm rate. That requires a long run in a real production environment with every alarm adjudicated afterwards, and it is the figure that decides whether a safety system survives contact with the people who have to work next to it.
It does not establish accuracy in absolute units. The gas channels self-calibrate against ambient air at power-on, on the assumption that the air is clean. That is a baseline, not a calibration - a traceable calibration is performed against reference gas of known concentration, which none of this work has involved.
And it does not establish anything about a hazardous or explosive atmosphere, which is a certification question rather than a testing one.
What a real validation would require
Set out here partly so a buyer can hold us to it and partly because it is the actual engineering plan.
- A documented methodology fixed before the data is collected: hardware revision, firmware revision, sensor batch, environment, event definition, and the metric being measured.
- Traceable calibration against certified reference gas, per element, with the calibration certificate retained.
- A controlled event series - known concentrations, known distances, known ventilation states - with enough repetitions per condition to put an interval around the result rather than a single number.
- A long unsupervised run in a real production environment, with every alarm and every non-alarm adjudicated afterwards against what actually happened.
- Publication of the setup, dataset, conditions, metrics, limitations, results and date together. A number without its methodology is not evidence, and we would rather publish nothing than publish that.
How we test the data itself
One part of this is genuinely reusable, so it is published rather than described.
The failure that costs a monitoring dataset the most is not a dramatic one. It is a channel that quietly stops changing, because a dead sensor and a perfectly quiet room produce the same flat line and neither one alarms. Close behind it is drift: a slow climb that eventually reaches any fixed threshold on its own.
Both are detectable in the data after the fact, and the tool we use to do it is open source, in the hazardx-tools repository. It reads a capture, reports stuck channels, gaps against the expected interval, values outside physical plausibility, and trends that are large against a channel's own noise but too slow to be an event. It exits non-zero when it finds something, so it runs in CI.
It is worth running against your own captures regardless of whose hardware produced them.
Why this page exists
Industrial safety buyers ask how a system was tested, and they are right to. Giving the honest answer plainly is worth more than a percentage nobody can reproduce.
A pilot deployment is how most of the gaps above actually close, which is why it is what we ask for rather than an order.